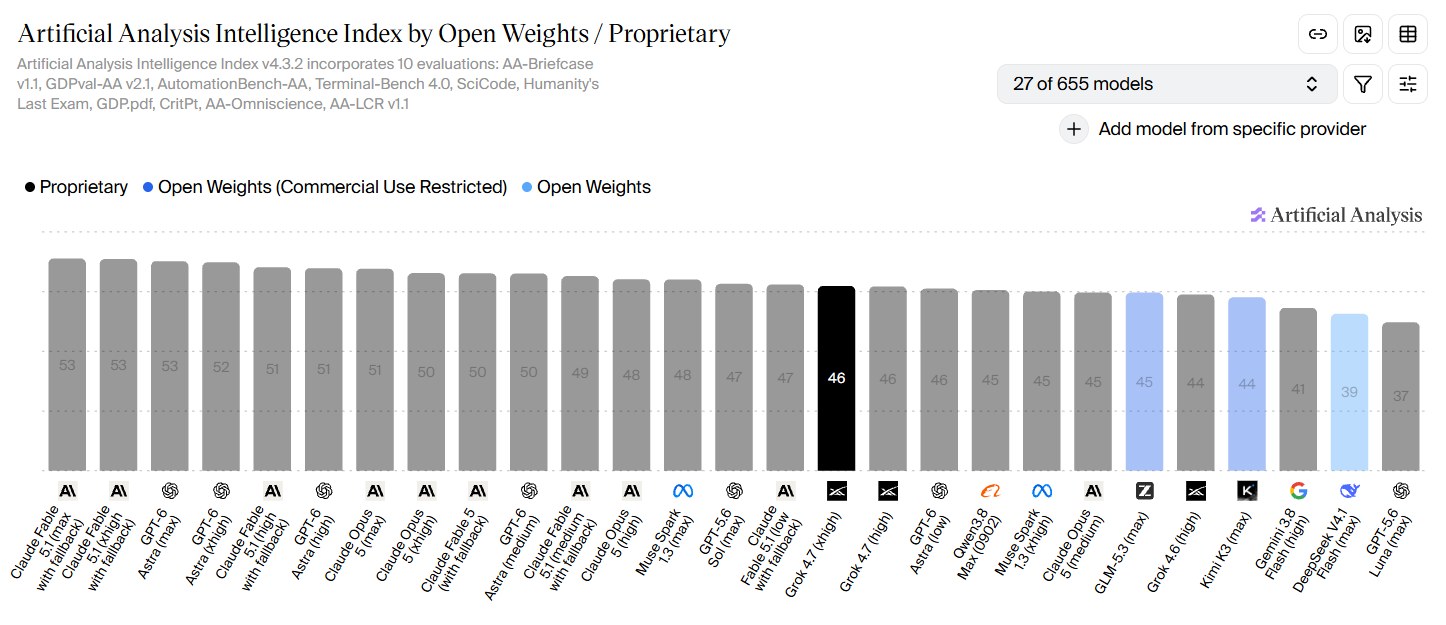
Elon Musk's xAI has rolled out Grok 4.7, marketing it as the company's pinnacle for coding and knowledge work. According to xAI, the system relies on an expanded base model, extended reinforcement learning, and built-in self-verification routines. To grease the wheels, xAI dropped API pricing to $2 per million input tokens and $6 per million output tokens, making access available through the Grok API, Cursor, and Grok Build. It is a desperate bid for market share disguised as generosity.
Independent evaluations tell a much harsher story about the model's actual standing. On the Artificial Analysis Intelligence Index (v4.3.2), Grok 4.7 limps in with a thoroughly mediocre score of 46 across ten combined benchmarks. Meanwhile, true market leaders sit comfortably at 53 points, rendering xAI's flagship offering an expensive mid-tier experiment.
The performance gap widens into a chasm on agentic coding benchmarks. On Terminal-Bench 4.0, Grok 4.7 manages a dismal 26 percent success rate, utterly humiliated by top-tier models and even edged out by budget competitors like DeepSeek V4.1 Flash at 27 percent. At a 26 percent completion rate, enterprise automation teams will find this model about as useful as a screen door on a submarine.
xAI's aggressive pricing is nothing less than a smoke screen, perfectly calibrated to match a product that simply cannot compete on raw intelligence.